A backtest takes a release and runs it against successful production decisions from the deployments of that release’s decision flow, reporting decisions that would change and, where the history includes outcomes, how the applications behind those decisions performed. It turns an assessment of safety into a measurable comparison.
- Where it lives
- Choosing the rows
- The baseline
- Adding realized outcomes
- Preview before you run
- Running, waiting, canceling
- Reading the result
- Earlier runs
- Limits worth knowing
Where it lives
Open a release, go to the Batch test tab, and set Data source to Decision archive (production data). The other option, Uploaded dataset, runs an ordinary batch test over a file you provide. The archive option requires a decision archive destination, and until one is connected, it is greyed out under "Connect a decision archive to analyze production data". See Production data and outcomes.
Choosing the rows
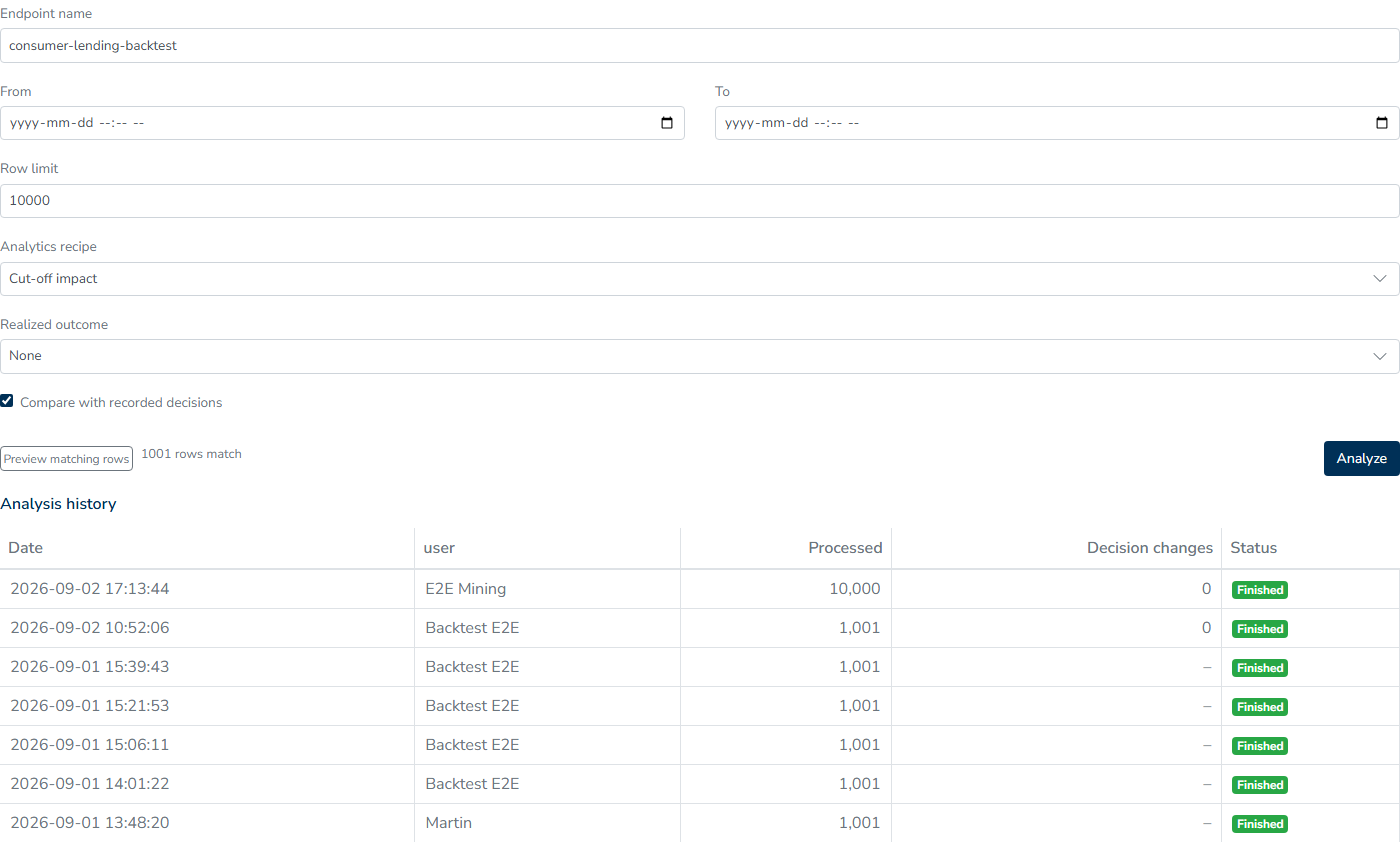
As soon as you choose the archive, a line shows how many decisions it holds for this release’s decision flow, the date range, and how many have each outcome. Only runs from deployments of this decision flow are included.
| Field | What it does |
|---|---|
| Endpoint name | Choose All of this decision flow’s endpoints to include every endpoint the flow is deployed on, or select one endpoint to narrow the rows further |
| From and To | The window on when the decision was received. Leave both empty for everything the archive holds, up to the row limit |
| Row limit | At most 50,000 rows, oldest first |
| Analytics recipe | Optional. Adds your own measures to the result, computed for both sides. See Analytics Recipes |
| Realized outcome | Shown from the start. Choose an outcome name from your history, or the form says when there is no outcome history |
The backtest reads successful production runs only, because a request that errored at the time has no decision available for comparison.
The baseline
Compare against lets you choose how to compare the release under test. Recorded decisions is selected by default. It uses what production actually returned and is fast.
Choose Replay both releases to replay the release under test and the release that decided each row over the same rows, with data sources switched off. This is slower, and every difference comes from the logic.
The result page states which comparison you selected.
Adding realized outcomes
Choose a Realized outcome to attach what happened next to each decision. This gives the Decision changes table context for interpretation: 92 approvals turning into declines is a volume, whereas 92 approvals turning into declines with a 6.5% bad rate, compared with 1.3% for the approvals that remained unchanged, is evidence about the proposed release.
Rows without a label remain in the run and in the decision counts, but they are excluded from the rates, and each cell reports how many of its rows had a label.
Preview before you run
Preview matching rows is optional. It counts rows using exactly the same filters as the run, so the preview count is the number of rows the run will process.
Running, waiting, canceling
Analyze queues the run for a background worker, and the page follows its progress from "Waiting for the analysis to start..." to a line repeating the submitted rows, dates, endpoint, outcome and comparison, followed by the count of processed rows against the total, such as "500 of 800 rows processed (62%)". You can leave the page because the run continues and appears under Analyses.
You can cancel a run while it is queued or running. A failed run remains in the list and explains the failure using the messages in Production data and outcomes.
Rows that cannot complete are counted as errors and reported beside the totals; they are excluded from every number rather than being treated as unchanged.
Reading the result
The result title uses the decision flow’s name and the release, such as “Consumer lending decision · consumer_lending_decision_2610130015”. Back returns to where you came from.
The headline shows how many decisions would change, such as “42 of 800 decisions would change.” The main change appears beneath it, such as “approve → decline: 42 of the 42 changes”.
The Decision changes table shows Baseline, Comparison, Count, Share of all rows, Realized rate (
Mine these rows on a changed row starts rule mining on those rows as a background job and opens the release’s Rule mining tab.
Analytics by slice shows each measure in the analytics recipe as a chart, with baseline and comparison side by side on the same axis. Its table shows Baseline, Comparison, Change, Relative change, and n, the row count on each side, such as “378 → 336”. Rates are percentages, a rate’s change is in percentage points, and the relative change is labelled “relative”.
At the bottom, Run again with another recipe starts a new run over the same rows with a different analytics recipe.
Earlier runs
Under the form, Analysis history lists this release's earlier archive analyses with their date, the person who started them, rows processed, decisions changed and status, so you can reopen a result instead of running the analysis again. Analyses in the left menu contains the same runs for every release and entity together.
Limits worth knowing
- A single run can contain at most 50,000 rows. For a larger book, take one window at a time. Because the results are rates, a stratified window is usually the more honest basis for comparison.
- Data sources are never called. If a decision flow depends on a live bureau response for a value that the request does not carry, the backtest may produce a different decision from production on both sides of the comparison. Lists are the exception: a backtest checks every list in the flow against the list as it stood when each request was received. See Lists.
- The archive contains the responses from your endpoints. Decisions made in test runs, batch tests or the case studio never enter it.